Speed is the axis everyone thinks they have mastered. Most teams have only pocketed it.
Every Indian child knows the story of the Samudra Manthan, the churning of the ocean for amrutha (divine elexir).
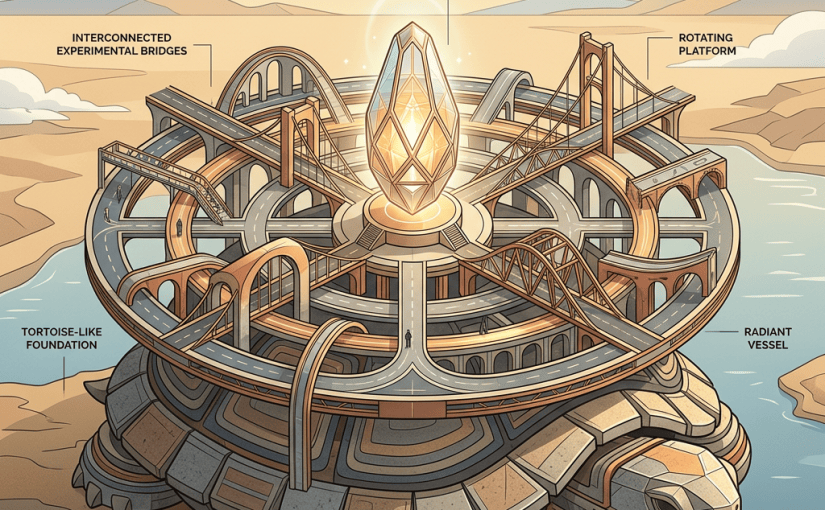
The devas (gods) and the asuras (demons), weakened and rivalrous, agree to churn the ocean together for amrutha, the nectar of immortality. Mount Mandara becomes the churning rod. Vāsuki, the serpent king, becomes the rope. When the mountain begins to sink into the ocean, Vishnu takes the form of Kūrma, the great tortoise, and holds it up from below.
The first thing the ocean gives them is not nectar. It is hālāhala, a poison so potent it threatens every world. Shiva drinks it and holds it in his throat, which turns blue. Only after that do the treasures come: the wish-granting cow, the celestial horse, Lakshmi herself. Amṛta comes last, carried by Dhanvantari.
I keep returning to this story because it is the most accurate description I know of what happens when you explore at speed.
The wrong lesson from speed
Speed is usually described as “the same work in less time” and treated as the least interesting kind of ambition. For most office work that is fair. For code, I think dismissing it hides the most important shift.
Watch what most teams actually do with agentic speed. A story that took three days now takes one. The team ships it, picks up the next story, and reports a velocity improvement. The design process is unchanged. One engineer still picks one approach, defends it in a review, and builds it.
That is pocketing the speed, not using it.
When a spike cost a sprint, running one and defending it was rational. When a spike costs an afternoon, the rational move is to run three and throw two away. The economics of exploration have changed. Most habits have not.
Terence Tao has described the same shift in mathematics: because AI makes it cheap to test whether an idea fails immediately, he now tries ideas he would once have dismissed as too unlikely to be worth the hours. That is speed used properly. Not faster delivery of the same bet, but more bets.
Churn wide
Here are the patterns I now ask teams to use.
Competing implementations. For any design question that would otherwise take a meeting, have agents build two or three alternatives in separate git worktrees, independent working copies of the same repository, so each agent has its own branch on disk. Then measure. A forty-minute argument about whether to cache at the edge or in the service becomes a benchmark you can read in five minutes.
Kill early. Use a cheap prototype not to prove an idea works but to find out fast whether it fails. Most of the poison should surface in the first hour.
Characterise before you change. Before an agent touches a legacy module, have it write characterisation tests that pin the current behaviour, warts and all. This used to be a week of tedium nobody funded. Now it is an afternoon, and it changes what is safe to attempt.
Exhaustive refactors. Renames, dependency upgrades and API migrations across a whole codebase used to be deferred indefinitely. They are now cheap enough to just do, if the oracle is strong enough to catch regressions.
Someone must hold the poison
The manthan has three roles we tend to forget.
Kūrma, the stable base. Without the tortoise, the mountain sinks and the churning stops. In engineering, Kūrma is your leaders grit, your build, your test harness and your reproducible environments. Parallel exploration on a wobbly foundation produces noise, not options.
Shiva, who holds the hālāhala. Exploration produces bad output first, and in volume. Someone must absorb it without letting it spread: discarding failed branches, refusing to merge the clever but unverified variant, saying no. That is a review discipline, and it is a cost. Ignore it and the poison reaches production.
Mohini, who serves the amṛta. Selection is not the end of the churning. When the pot of nectar finally rose from the ocean, the devas and asuras fought over it, each side certain it was theirs. Vishnu took the form of Mohini and settled the fight not by argument but by controlling distribution. She seated everyone in rows and served the nectar herself, one row at a time.
This is the step most teams skip. The winning branch is the amṛta, but merging it is not the same as serving it. Mohini is progressive delivery: the change goes behind a feature flag to 1% of traffic, then 10%, then everyone. The argument about whether it really is the winner is settled by what real users experience, not by whoever argued best in review.
Rāhu, who slipped into the line. One asura, Rāhu, disguised himself as a deva and sat in the devas’ row. Before the Sun and the Moon recognised him, he had swallowed a sip. Vishnu’s discus severed his head, but the nectar had already passed his throat. The head lived on, and it still returns to swallow the Sun and the Moon at every eclipse.
Three lessons, in order.
- Disguise gets past selection. The branch that won the benchmark by caching stale data looks like a deva until it meets real traffic.
- You need watchers in the line. The Sun and Moon of your pipeline are canary analysis: comparing the cohort that received the change with the one that did not, on error rates, latency and the business metric that would reveal a disguise.
- The discus is not enough. Rollback cuts the change off, but whatever it already swallowed stays immortal: rows written, messages sent, caches filled, schemas migrated. So serve only what you can take back. Use expand-and-contract migrations (add the new schema beside the old, switch over, remove the old later), idempotent writes, and flags that turn the new path off without a redeploy. If Rāhu’s head survives, make sure it has nothing to eclipse.
Explore wide, merge narrow
The cost model has inverted. Tokens are cheap. Review attention is not. So the rule becomes: explore as widely as the oracle can judge, merge only what the oracle has judged, and serve it the way Mohini did, one row at a time.
This is also where I warned, in an earlier post on “-maxxing” anti-patterns, about loopmaxxing: running agents in ever-longer loops because you can. Parallelism without a selection mechanism is just loopmaxxing in several directions at once. Churn without selection and staged serving ends where the story’s churn did: in a fight over the pot.
For the Weekend
Pick the next design question your team would normally argue about. Instead of a meeting, write down how you would measure the answer. Then have agents build the two or three leading options and run the measurement.
Example. Suppose the team is split on how to cache product prices. One camp wants Redis, an in-memory data store beside the service. The other wants caching at the CDN edge, the content delivery network’s servers close to users. Instead of a meeting, run the churn.
Step 1: write the measurement before any code. This is the selection mechanism, Mohini’s job, and it is agreed first:
USER STORYAs the tech lead, I want an agreed, automated way to compare price-cachingdesigns, so that the team decides on evidence instead of opinion.DEFINITION OF READY- A staging environment with production-like traffic replay is available.- An admin API to change a price (admin.set_price) exists.DEFINITION OF DONE- bench/README.md defines four measures: p95 latency at 500 requests a second for 5 minutes; staleness (seconds from a price change until every reader sees it); estimated monthly cost at current traffic; behaviour when the cache layer is down.- bench/load.js (k6) and bench/staleness.py implement the first two.- bench/run.sh runs both against a BASE_URL and prints raw results.- You MUST NOT implement any cache.DEFINITION OF SUCCESS- Two runs of bench/run.sh against current main agree within 10%, proving the measurement itself is stable.
Step 2: two worktrees, two agents. A worktree is an extra working copy of the same repository on its own branch:
git worktree add ../prices-redis -b spike/prices-redisgit worktree add ../prices-edge -b spike/prices-edge
Each agent gets the same story, with the cache-specific lines changed:
USER STORYAs the tech lead, I want a working Redis price cache in this worktree,so that it can be measured against the CDN option.[CDN agent: "a working CDN edge price cache"]DEFINITION OF READY- bench/ is on main, and bench/run.sh works against staging.- This worktree is on branch spike/prices-redis. [CDN agent: spike/prices-edge]DEFINITION OF DONE- A Redis cache for GET /prices/{sku}, with a 30-second TTL (time to live) and explicit invalidation on a price change. [CDN agent: Cache-Control: s-maxage=30, plus a purge call on change]- The cache sits behind the PRICE_CACHE_MODE setting, default off.- You MUST NOT edit anything under bench/.DEFINITION OF SUCCESS- bench/run.sh completes, and its raw output is pasted into your report unedited.
Step 3: the shared oracle. The load test uses k6, a load-testing tool scripted in JavaScript:
import http from 'k6/http';import { check } from 'k6';export const options = { scenarios: { steady: { executor: 'constant-arrival-rate', rate: 500, timeUnit: '1s', duration: '5m', preAllocatedVUs: 200, }, }, thresholds: { http_req_duration: ['p(95)<120'] },};export default function () { const sku = `sku-${Math.floor(Math.random() * 5000)}`; const res = http.get(`${__ENV.BASE_URL}/prices/${sku}`); check(res, { 'status is 200': (r) => r.status === 200 });}
And the staleness probe:
import time, requestsdef staleness_seconds(base_url, admin, sku, new_price, timeout=120): admin.set_price(sku, new_price) start = time.monotonic() while time.monotonic() - start < timeout: if requests.get(f"{base_url}/prices/{sku}").json()["price"] == new_price: return time.monotonic() - start time.sleep(0.25) raise AssertionError(f"{sku} still stale after {timeout}s")
Step 4: let the numbers choose. An illustrative result:
| Option | p95 latency | Worst staleness | Cache layer down |
|---|---|---|---|
| Redis | 38 ms | 0.8 s | Falls back to the database; p95 rises to 210 ms |
| CDN edge | 22 ms | 31 s (purge is asynchronous) | Requests go to origin; no errors |
Now the real question is visible. It was never Redis versus CDN. It is whether a customer may ever see a price that is 30 seconds out of date. That is a product decision, and it takes five minutes once the numbers are on the table. The losing worktree is deleted with git worktree remove ../prices-edge. Shiva holds the poison; nothing reaches main.
Step 5: serve the amṛta. Suppose the product decision is that 30 seconds of staleness is unacceptable, so Redis wins. Merging the branch is not the end of it:
USER STORYAs the tech lead, I want the Redis price cache rolled out in stages, sothat if it misbehaves under real traffic, only a small cohort is affectedand we can take it back.DEFINITION OF READY- spike/prices-redis is merged behind PRICE_CACHE_MODE, default off.- Dashboards show price-endpoint error rate, p95 latency and "price mismatch at checkout" events, split by flag cohort.- Turning the flag off restores the old path with nothing to clean up: the cache only reads, and writes nothing the old path depends on.DEFINITION OF DONE- Flag enabled for 1% of SKUs, then 10%, 50% and 100%, with at least 24 hours at each stage.- Before each step up, compare the cohort with the flag on against the cohort with it off.- Automatic rollback: if checkout price mismatches in the on-cohort exceed the off-cohort's by more than 0.1 percentage points, or p95 latency exceeds 120 ms for 10 minutes, turn the flag off and open an incident.- You MUST NOT change the rollback thresholds.DEFINITION OF SUCCESS- 100% rollout reached with no automatic rollback, and checkout price mismatches no higher than before the change.
The checkout-mismatch metric is the Sun and the Moon. It is the one place a stale price gives itself away, however well it did in the benchmark. And the DoR line about nothing to clean up is the answer to Rāhu’s head: this rollout can be fully taken back.
If you cannot say how you would measure it, you have discovered something more valuable than the answer: the oracle you are missing.